NVIDIA and Supermicro AI systems delivered in 4 to 5 weeks: HGX H100/H200 servers, SuperClusters and GB200 NVL72. Data sheets and quotes.
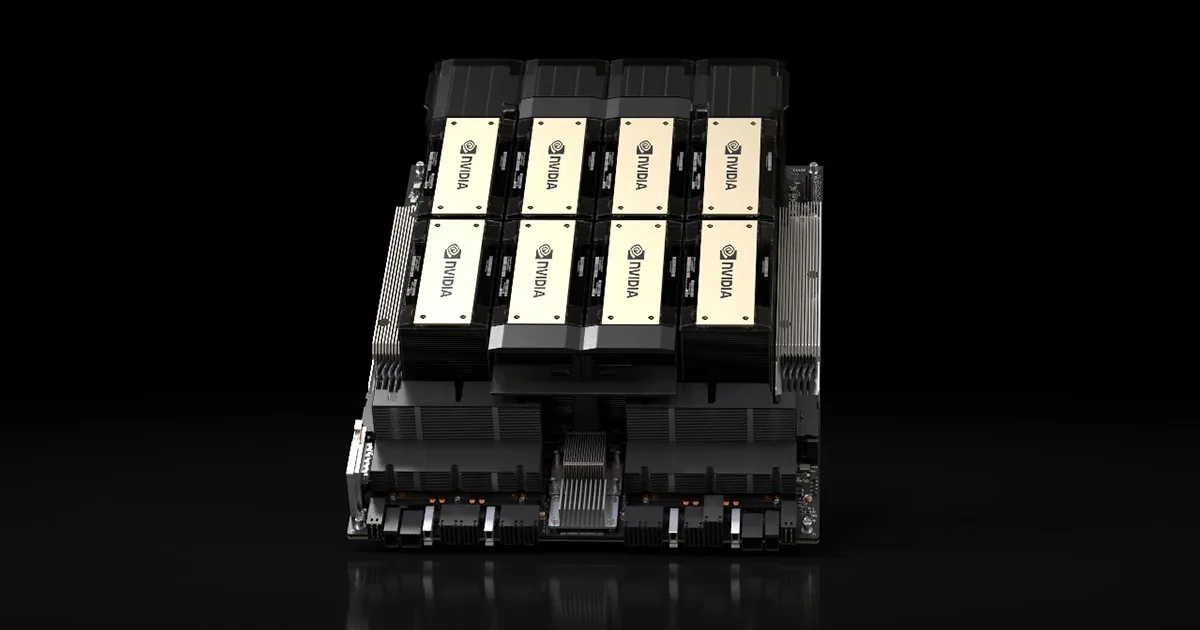
The first GPU with HBM3e memory: 141GB at 4.8TB/s, nearly double the H100 and 1.4× the bandwidth, paired with Supermicro HGX servers.
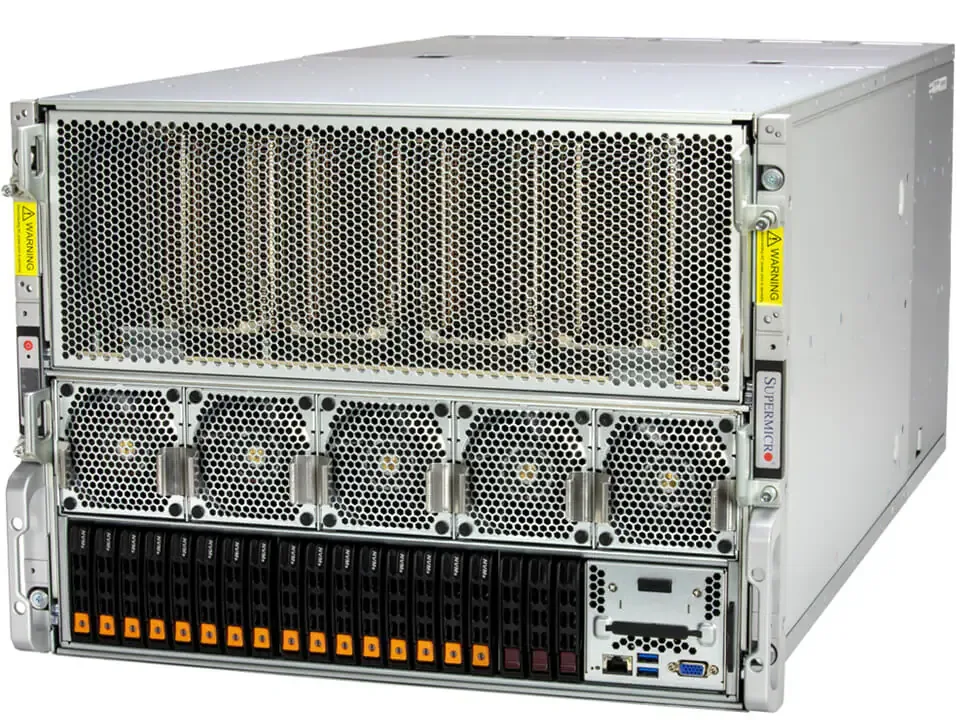
8U GPU SuperServer for demanding AI and HPC: up to 8 NVIDIA HGX H100 or H200 GPUs, 32 DDR5 DIMM slots, up to 8TB of memory, PCIe 5.0 expansion and extensive storage.
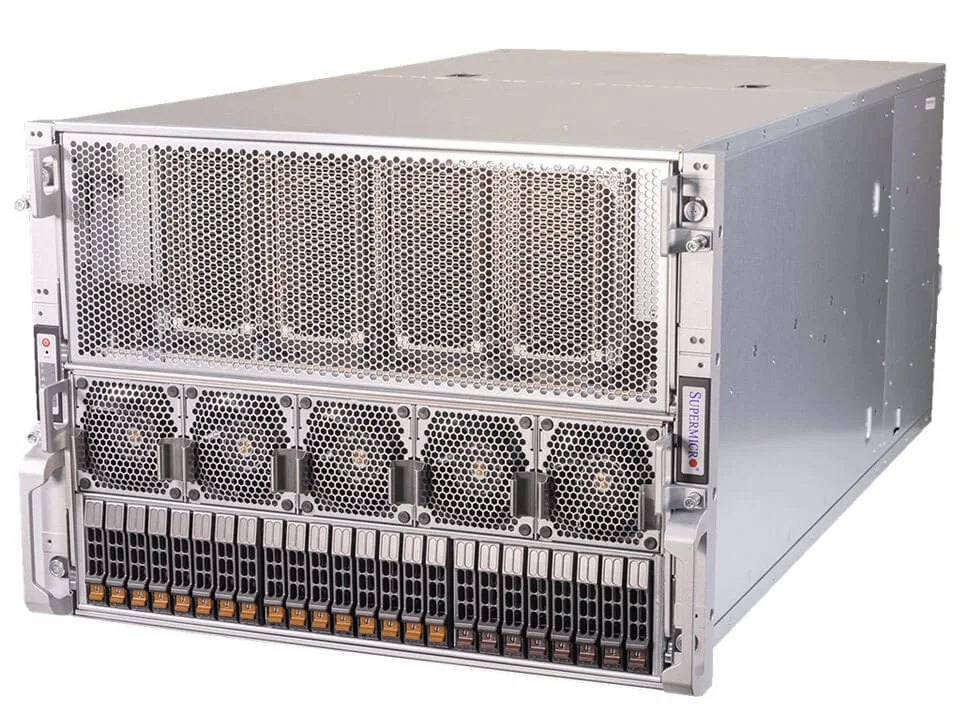
8U high-density system for NVIDIA HGX H100 or H200 8-GPU configurations: 24 DDR5 DIMM slots up to 6TB, 12 hot-swap 2.5" NVMe bays and flexible networking.
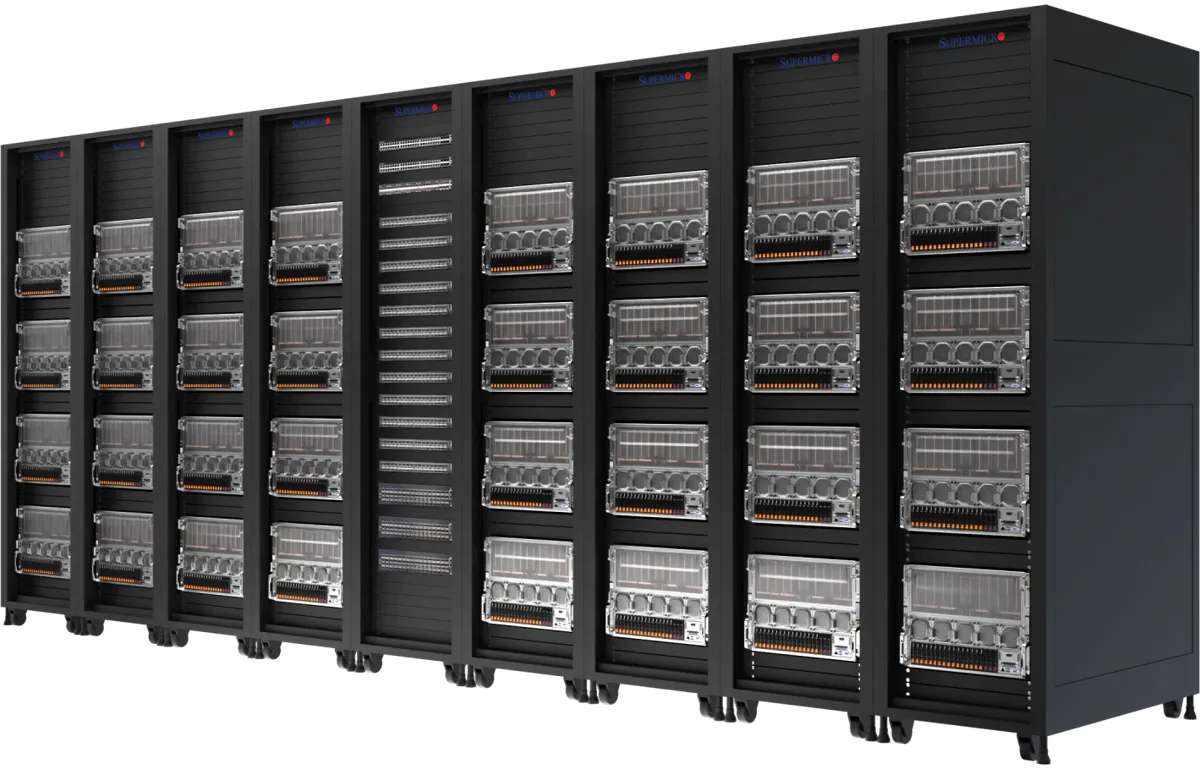
Scalable, air-cooled 32-node cluster of NVIDIA HGX H200 8-GPU systems, built for generative AI, large language models and HPC.
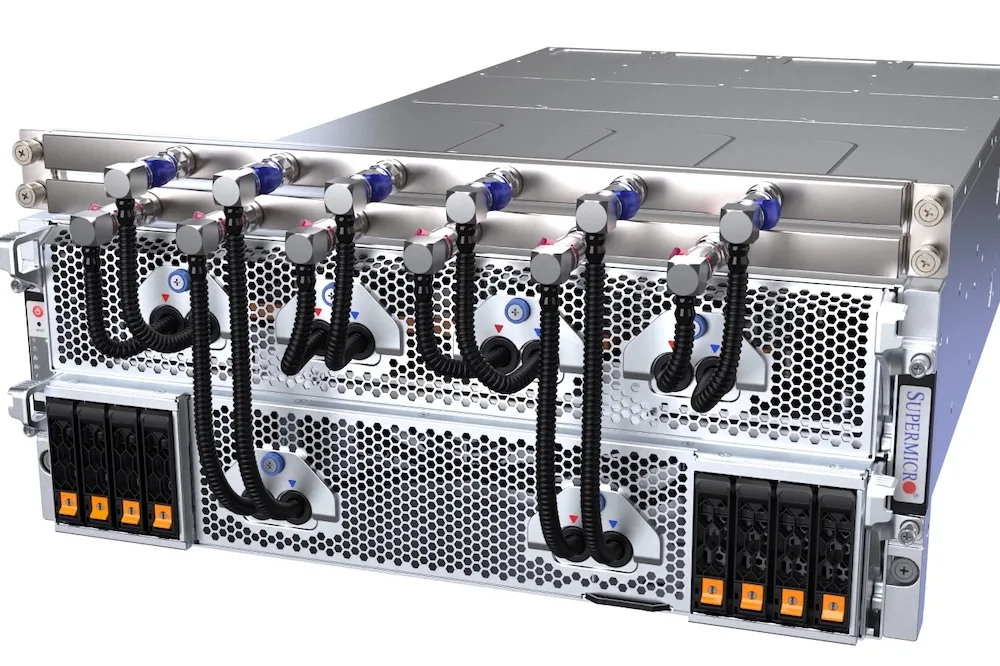
Rack-scale plug-and-play solution supporting up to 256 NVIDIA HGX H100 or H200 GPUs across multiple racks, with advanced liquid cooling for large-scale AI training and HPC.
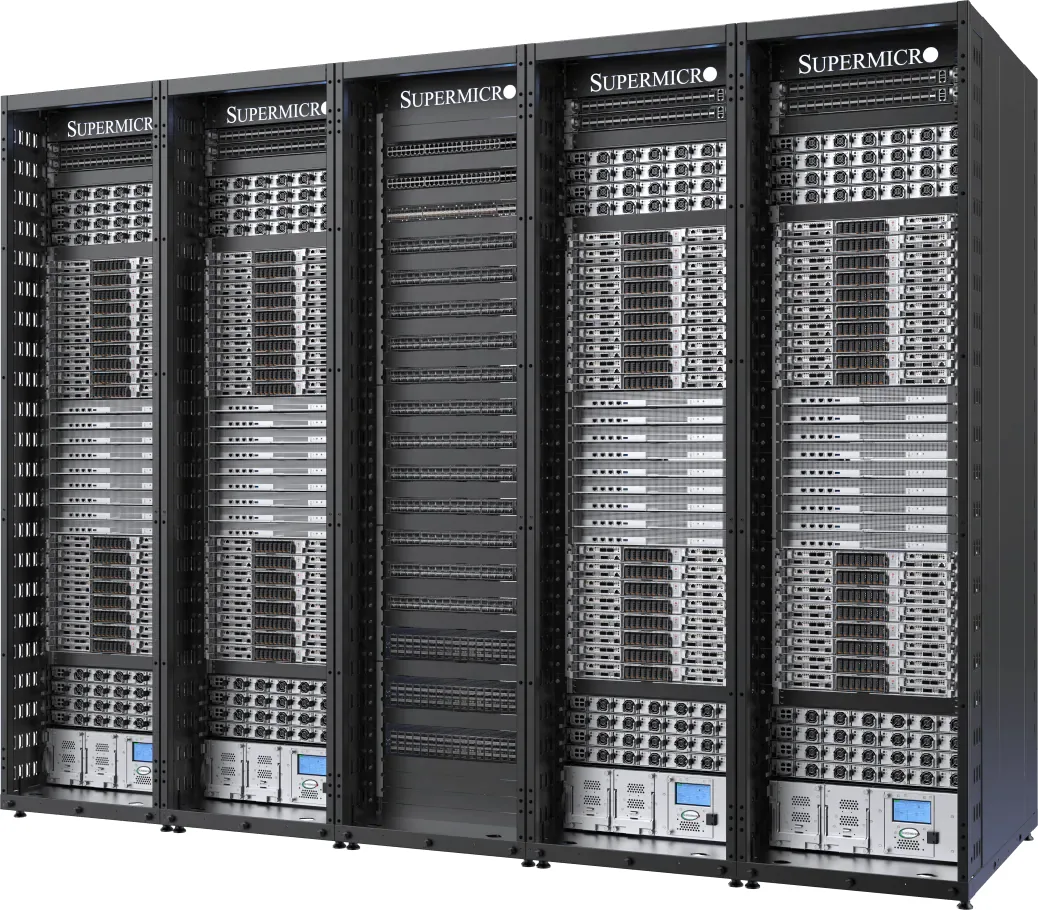
The most powerful and efficient NVIDIA Blackwell platform: 72 GPUs acting as one in a single liquid-cooled rack, up to 25× the performance at the same power as the previous generation.
Configured for your workload and delivered in 4 to 5 weeks. Tell us your interests and we will arrange a personal consultation.