Home › Systems › Liquid-cooled AI SuperCluster
256 GPUs · DLC

Liquid-cooled AI SuperCluster

Rack-scale plug-and-play solution supporting up to 256 NVIDIA HGX H100 or H200 GPUs across multiple racks, with advanced liquid cooling for large-scale AI training and HPC.
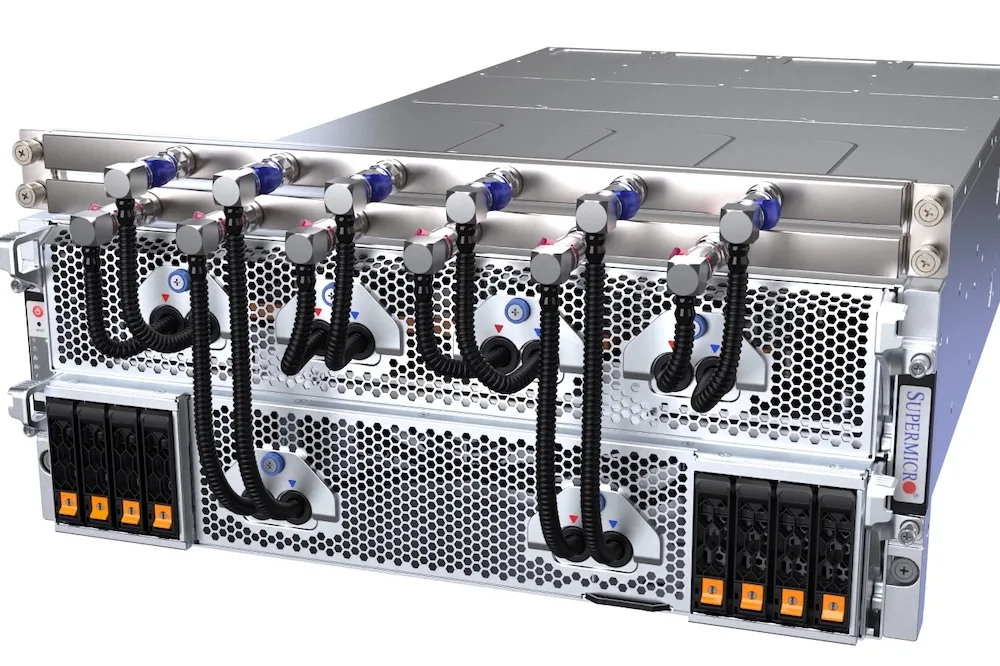
Liquid-cooled AI SuperCluster
256 GPUs32× 4U liquid-cooled nodes
5 racksvs 9 air-cooled
~40% lesscooling energy
CDU includedin-rack coolant units

Key features

Up to 256 NVIDIA HGX H100/H200 GPUsDesigned for large-scale AI and HPC workloads.
Advanced liquid coolingHigher energy efficiency and system performance for massive GPU deployments.
Rack-scale deploymentStreamlined plug-and-play solution for rapid deployment.
Optimised for AI and HPCIdeal for large-scale training and compute-intensive applications.
Delivered in 4 to 5 weeksSuperServer.ai delivers against an industry norm of two months or more.

Same GPUs, half the floor space

The liquid-cooled SuperCluster uses Supermicro's 4U direct-to-chip nodes, each with eight HGX H100 or H200 GPUs and cold plates on GPUs, CPUs and switches. Rack-level coolant distribution units are included. The result is the same 256-GPU cluster in five racks instead of nine, with lower fan power and a data-centre PUE that is often the difference between being allowed to deploy and not.

When liquid is the right call

  • Your colocation provider limits you on power per rack or floor space.
  • Energy cost is a line item you are measured on.
  • You are planning for Blackwell: the GB200 NVL72 is liquid-cooled only, so building the plumbing now is not wasted.

What we check in the quote

  • Facility water availability and temperature, or whether a liquid-to-air CDU is needed.
  • Commissioning and maintenance terms for the cooling loop.
  • Like-for-like comparison against the air-cooled cluster so the premium is visible.
Get a quote for the Liquid-cooled SuperCluster

Configured for your workload and delivered in 4 to 5 weeks. Tell us your interests and we will arrange a personal consultation.

Brief us & book a call

Powering AI. Delivered fast.

Tell us what you're building. Whether you're scaling a generative AI cluster, training trillion-parameter models, or futureproofing for multi-node inference, we'll configure, quote, and deliver the right infrastructure fast.

Our team will review your submission and respond within 1 business day. For qualified projects, we'll set up a Zoom call with one of our technical specialists.

About you
Who should we contact?
We'll only use this to follow up on your briefing.
Company or institution name.
Helps us understand who you are.
Your project
The more you share, the better we can help.
Prefer to talk? Upload a voice message with any extra context and we'll transcribe and review it. Max 20MB. MP3, WAV or M4A.
They may be eligible for our referral programme.
Would you like to book a call with our team?

We offer 30-minute Zoom briefings for serious projects.

We use your details only to respond to your brief. Privacy.