Home › Systems › NVIDIA H200 Tensor Core GPU
GPU · SXM5

NVIDIA H200 Tensor Core GPU

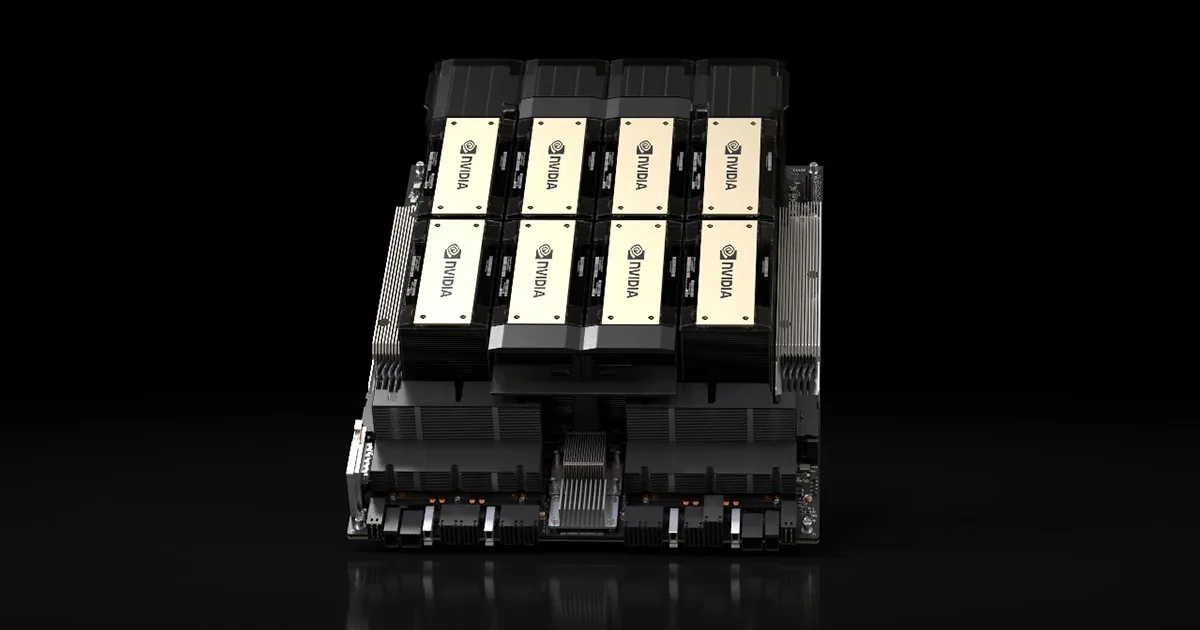
The first GPU with HBM3e memory: 141GB at 4.8TB/s, nearly double the H100 and 1.4× the bandwidth, paired with Supermicro HGX servers.
NVIDIA H200 Tensor Core GPU
141 GBHBM3e memory
4.8 TB/smemory bandwidth
700 WSXM TDP
NVLink 900 GB/sGPU-to-GPU

Key features

Cutting-edge performanceNVIDIA Tensor Core architecture accelerates AI training and inference with unprecedented speed and precision.
Seamless scalabilityUp to 8 GPUs connected with NVLink and NVSwitch for lightning-fast GPU-to-GPU communication.
Optimised for AI innovationMassive language models, scientific simulation and advanced analytics on one platform.
Efficient designIndustry-leading performance per watt for large-scale data centres and AI deployments.
Advanced networking readyBlueField-3 SuperNIC, Spectrum-X, Quantum-2 and next-generation 800Gb/s platforms.
Delivered in 4 to 5 weeksSuperServer.ai delivers against an industry norm of two months or more.

What the H200 changes

The H200 is the same Hopper compute die as the H100 with 141GB of HBM3e in place of 80GB of HBM3, and 4.8TB/s of bandwidth in place of 3.35TB/s. For inference on large language models that is the difference between a 70B model at a real batch size on a single GPU and needing two. For training, the extra memory lets you hold larger activations and cut gradient checkpointing.

Who buys it

  • Inference teams serving 70B-class models where memory, not FLOPS, is the limit.
  • Fine-tuning shops that want to stay on one node.
  • Anyone upgrading an existing HGX H100 chassis: H200 is a drop-in SXM5 module in the same 8-GPU baseboard.

How it is sold

The H200 is not sold as a loose card for practical purposes. It ships inside an HGX 8-GPU baseboard in systems such as the SYS-821GE-TNHR and AS-8125GS-TNHR. Cloud pricing for H200 by the hour is on our price comparison.

Get a quote for the H200 GPU

Configured for your workload and delivered in 4 to 5 weeks. Tell us your interests and we will arrange a personal consultation.

Brief us & book a call

Powering AI. Delivered fast.

Tell us what you're building. Whether you're scaling a generative AI cluster, training trillion-parameter models, or futureproofing for multi-node inference, we'll configure, quote, and deliver the right infrastructure fast.

Our team will review your submission and respond within 1 business day. For qualified projects, we'll set up a Zoom call with one of our technical specialists.

About you
Who should we contact?
We'll only use this to follow up on your briefing.
Company or institution name.
Helps us understand who you are.
Your project
The more you share, the better we can help.
Prefer to talk? Upload a voice message with any extra context and we'll transcribe and review it. Max 20MB. MP3, WAV or M4A.
They may be eligible for our referral programme.
Would you like to book a call with our team?

We offer 30-minute Zoom briefings for serious projects.

We use your details only to respond to your brief. Privacy.