Home › Systems › NVIDIA GB200 NVL72
rack-scale · Blackwell

NVIDIA GB200 NVL72

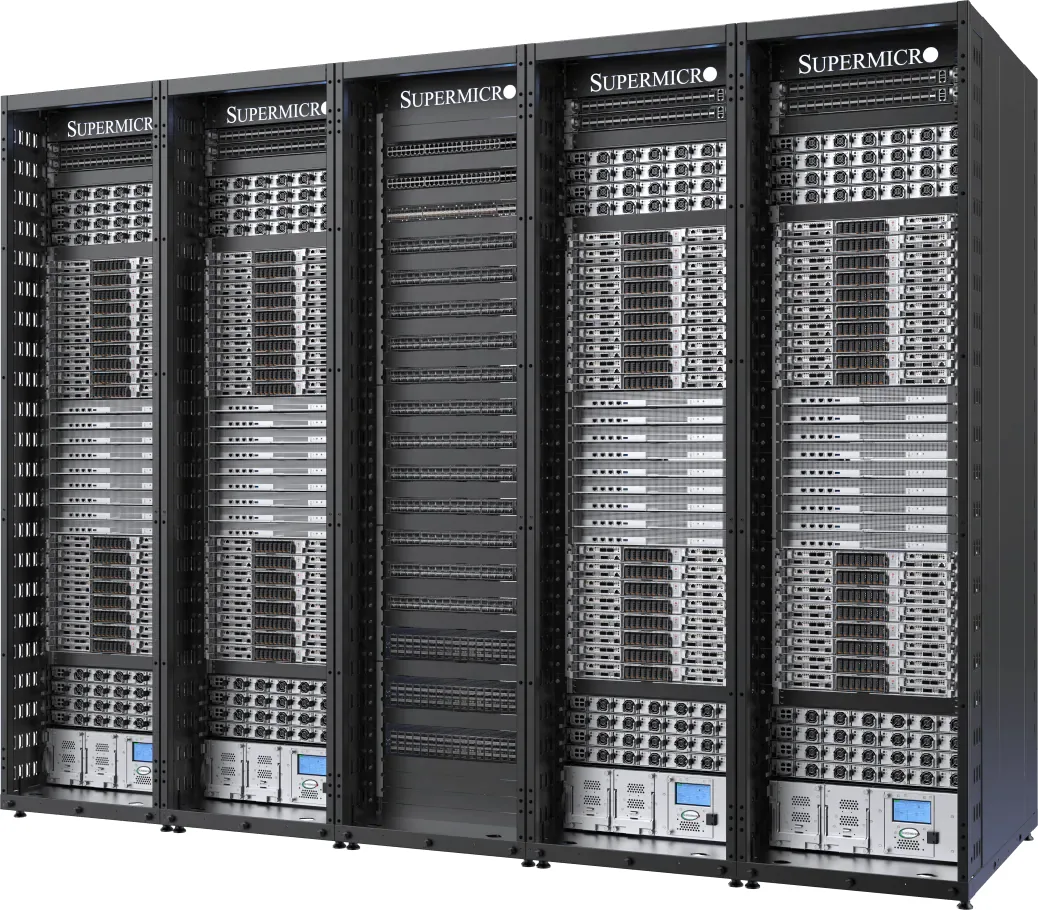
The most powerful and efficient NVIDIA Blackwell platform: 72 GPUs acting as one in a single liquid-cooled rack, up to 25× the performance at the same power as the previous generation.
NVIDIA GB200 NVL72
72× B20036 Grace CPUs
13.5 TBHBM3e in one NVLink domain
130 TB/sNVLink bandwidth
~120 kWper rack, liquid-cooled

Key features

72 NVIDIA Blackwell GPUsActing as a single GPU with a massive pool of HBM3e memory for exascale efficiency in one rack.
Pioneers in liquid coolingSupermicro end-to-end liquid cooling cuts data-centre electricity costs by up to 40%.
Unmatched manufacturing scaleRack-level liquid-cooling production in San Jose, Europe and Asia for timely, high-quality deployments.
Advanced networking readyBlueField-3 SuperNIC, Spectrum-X, Quantum-2 and next-generation 800Gb/s platforms.
Delivered in 4 to 5 weeksSuperServer.ai delivers against an industry norm of two months or more.

One rack as one GPU

GB200 NVL72 connects 72 Blackwell GPUs and 36 Grace CPUs into a single NVLink domain, so a trillion-parameter model sees the whole rack as one accelerator. NVIDIA's own figure is roughly 30 times the real-time inference throughput of an equivalent H100 cluster on the largest models, at a fraction of the energy per token. It ships only as a liquid-cooled rack, built by Supermicro and other partners to NVIDIA's reference design.

Who it is for

  • Frontier-scale training and inference on models above the 400B class.
  • Providers selling Blackwell capacity by the hour.
  • Nobody running 70B models: an H200 node does that for far less.

The facility question comes first

  • Around 120kW per rack means most existing European colocation halls cannot host it without an upgrade. We check this before quoting.
  • Facility water or CDU capacity is mandatory.
  • Allocation is still tight; lead times are quoted case by case.

Cloud pricing for B200 by the hour is on our price comparison if you want the capacity without the building work.

Get a quote for the GB200 NVL72

Configured for your workload and delivered in 4 to 5 weeks. Tell us your interests and we will arrange a personal consultation.

Brief us & book a call

Powering AI. Delivered fast.

Tell us what you're building. Whether you're scaling a generative AI cluster, training trillion-parameter models, or futureproofing for multi-node inference, we'll configure, quote, and deliver the right infrastructure fast.

Our team will review your submission and respond within 1 business day. For qualified projects, we'll set up a Zoom call with one of our technical specialists.

About you
Who should we contact?
We'll only use this to follow up on your briefing.
Company or institution name.
Helps us understand who you are.
Your project
The more you share, the better we can help.
Prefer to talk? Upload a voice message with any extra context and we'll transcribe and review it. Max 20MB. MP3, WAV or M4A.
They may be eligible for our referral programme.
Would you like to book a call with our team?

We offer 30-minute Zoom briefings for serious projects.

We use your details only to respond to your brief. Privacy.