Home › Systems › 32-node HGX H200 SuperCluster
256 GPUs · air-cooled

32-node HGX H200 SuperCluster

Scalable, air-cooled 32-node cluster of NVIDIA HGX H200 8-GPU systems, built for generative AI, large language models and HPC.
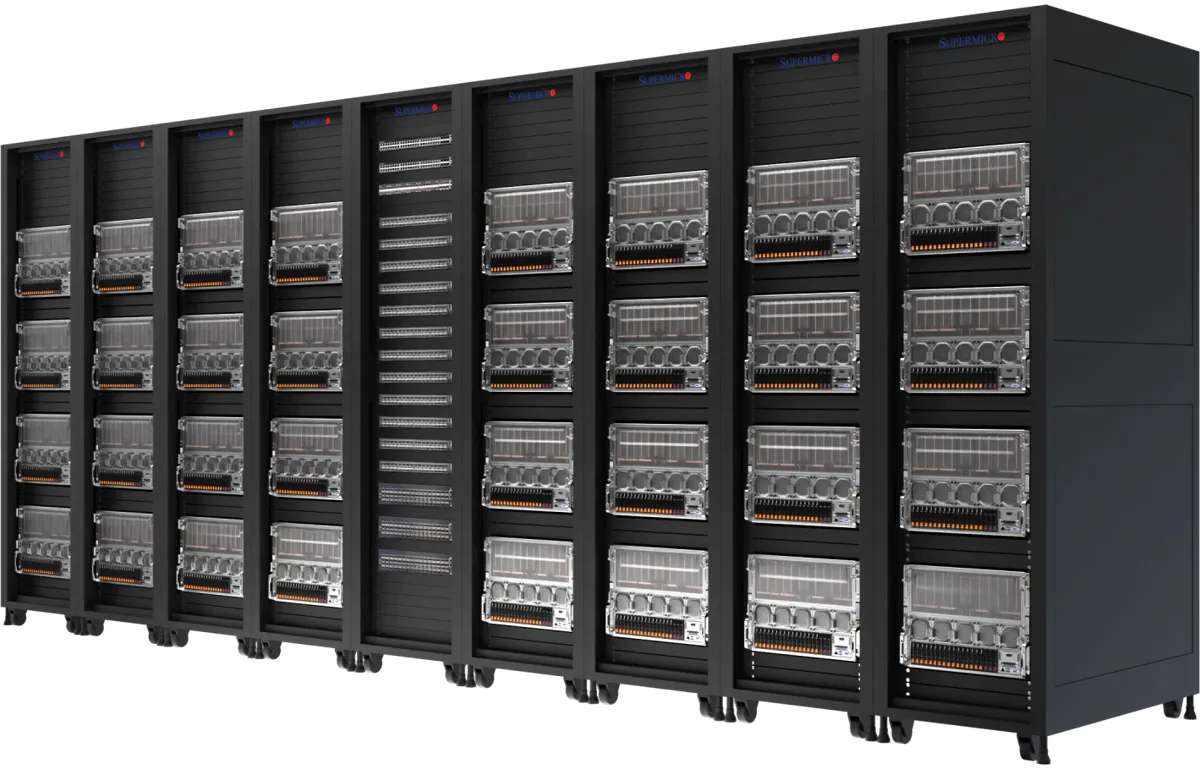
32-node HGX H200 SuperCluster
256× H20032 nodes × 8 GPUs
36 TBHBM3e total
400G NDR1:1 GPU-to-network
9 racksair-cooled, validated

Key features

256 NVIDIA HGX GPUsUp to 36TB HBM3e memory and 900GB/s NVLink for ultra-fast GPU-to-GPU communication.
Industry-leading scalabilitySpine-leaf network fabric scales from 32 nodes (256 GPUs) to thousands of nodes.
1:1 networking to GPUs400Gbps NVIDIA GPUDirect RDMA and storage for low-latency, high-throughput performance.
Plug-and-play deploymentPre-tested and validated for rapid setup of large-scale AI infrastructure.
Delivered in 4 to 5 weeksSuperServer.ai delivers against an industry norm of two months or more.

A cluster delivered as one product

Supermicro's SuperCluster packages 32 eight-GPU HGX H200 nodes with the spine-leaf NVIDIA Quantum-2 InfiniBand fabric, management nodes, storage connectivity and rack power, pre-cabled and pre-validated. You take delivery of a working 256-GPU cluster rather than 32 servers and a switching bill of materials. It scales in further 32-node units.

Who buys it

  • Companies training models in the tens of billions of parameters and above, where the interconnect is the bottleneck.
  • Cloud and inference providers standing up capacity in a European data centre.
  • Research organisations replacing an ageing HPC cluster.

Before you ask for a quote

  • Confirm the data centre can take roughly 40kW per rack air-cooled. If not, look at the liquid-cooled version, which fits in five racks.
  • Decide on storage: most buyers pair it with a parallel file system, which we can quote alongside.
  • Lead time on a full SuperCluster is longer than on single nodes. Ask early.
Get a quote for the HGX H200 SuperCluster

Configured for your workload and delivered in 4 to 5 weeks. Tell us your interests and we will arrange a personal consultation.

Brief us & book a call

Powering AI. Delivered fast.

Tell us what you're building. Whether you're scaling a generative AI cluster, training trillion-parameter models, or futureproofing for multi-node inference, we'll configure, quote, and deliver the right infrastructure fast.

Our team will review your submission and respond within 1 business day. For qualified projects, we'll set up a Zoom call with one of our technical specialists.

About you
Who should we contact?
We'll only use this to follow up on your briefing.
Company or institution name.
Helps us understand who you are.
Your project
The more you share, the better we can help.
Prefer to talk? Upload a voice message with any extra context and we'll transcribe and review it. Max 20MB. MP3, WAV or M4A.
They may be eligible for our referral programme.
Would you like to book a call with our team?

We offer 30-minute Zoom briefings for serious projects.

We use your details only to respond to your brief. Privacy.